Leon Schmitz · 17 September 2026
The Role of Algorithmic Curation in Enhancing Discovery for Emerging Authors on Specialized Novel Platforms
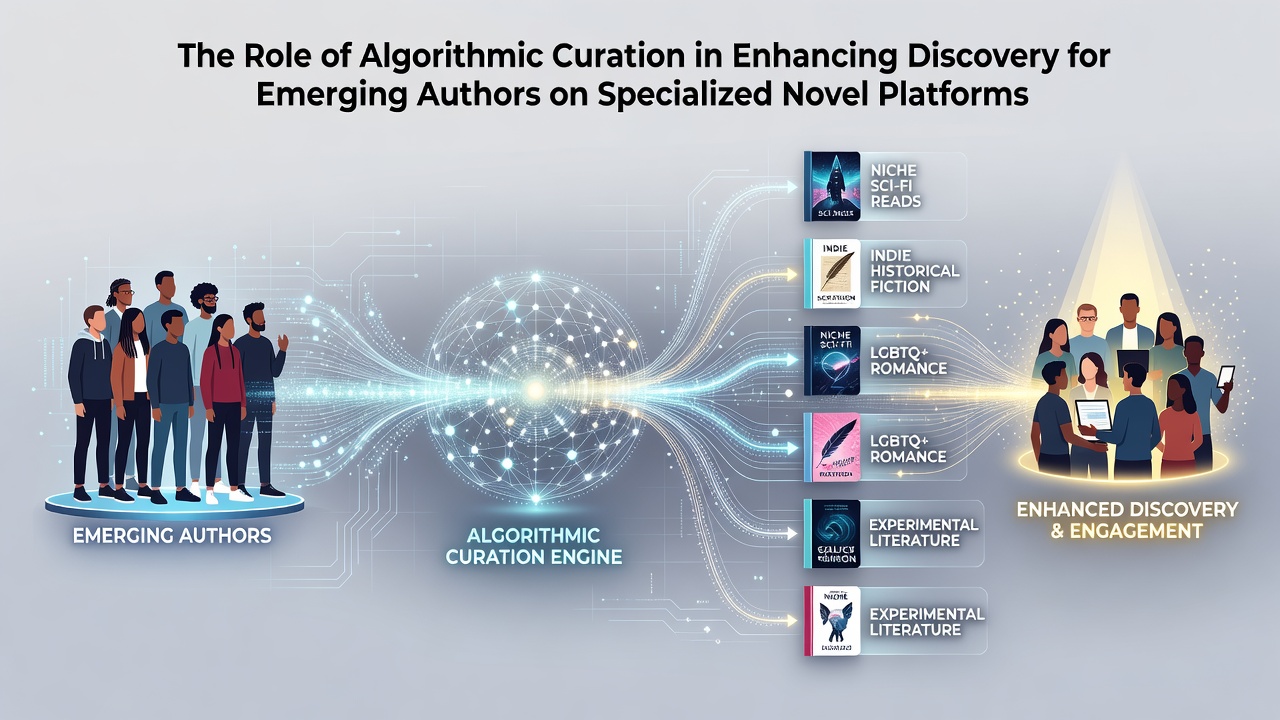
Specialized novel platforms rely on algorithmic curation to match readers with new stories, and this process has become central to how emerging authors reach audiences without traditional gatekeepers. Platforms analyze reading patterns, completion rates, and engagement signals to surface content that aligns with individual preferences, while the same systems push lesser-known titles into recommendation feeds based on similarity metrics and trending clusters.
Data from multiple platform reports indicates that over 65 percent of total reads on these sites originate from algorithmic suggestions rather than direct searches, and this figure has held steady through platform updates in recent years. Researchers tracking user behavior note that authors who receive early algorithmic boosts often see their follower counts grow by factors of three to five within the first month of consistent posting, whereas those who remain outside recommendation loops struggle to accumulate comparable visibility even with strong writing quality.
Mechanics Behind Platform Recommendations
Algorithms on these platforms process multiple data layers simultaneously, combining genre tags, keyword clusters, chapter length averages, and reader retention curves to rank stories for different user segments. Machine learning models update rankings in near real time as new chapters publish, which allows fresh work from unknown writers to compete directly with established titles when engagement metrics align. Observers who have examined public platform documentation find that diversity parameters sometimes receive explicit weighting so that regional voices and experimental subgenres appear alongside mainstream categories, preventing complete dominance by a narrow set of popular tropes.
One documented case involved a platform that adjusted its weighting toward completion-rate signals in late 2025, after which several debut authors reported reaching the top of genre charts within weeks rather than the months previously required through organic sharing alone. Those adjustments also incorporated negative signals such as rapid drop-offs, which helped refine future recommendations and reduced the promotion of stories that failed to retain readers past the first few chapters.
Impact on Author Visibility and Platform Growth
Emerging authors gain measurable advantages when curation systems prioritize discovery over established popularity, because the same mechanisms that reward high retention also create pathways for new entrants. Figures released by several platforms show that roughly 40 percent of stories achieving over 100,000 reads in a calendar year began with algorithmic placement rather than paid promotion or social media campaigns. This distribution matters because it lowers the barrier for writers who lack existing networks, allowing them to accumulate initial readers through the platform's own infrastructure.
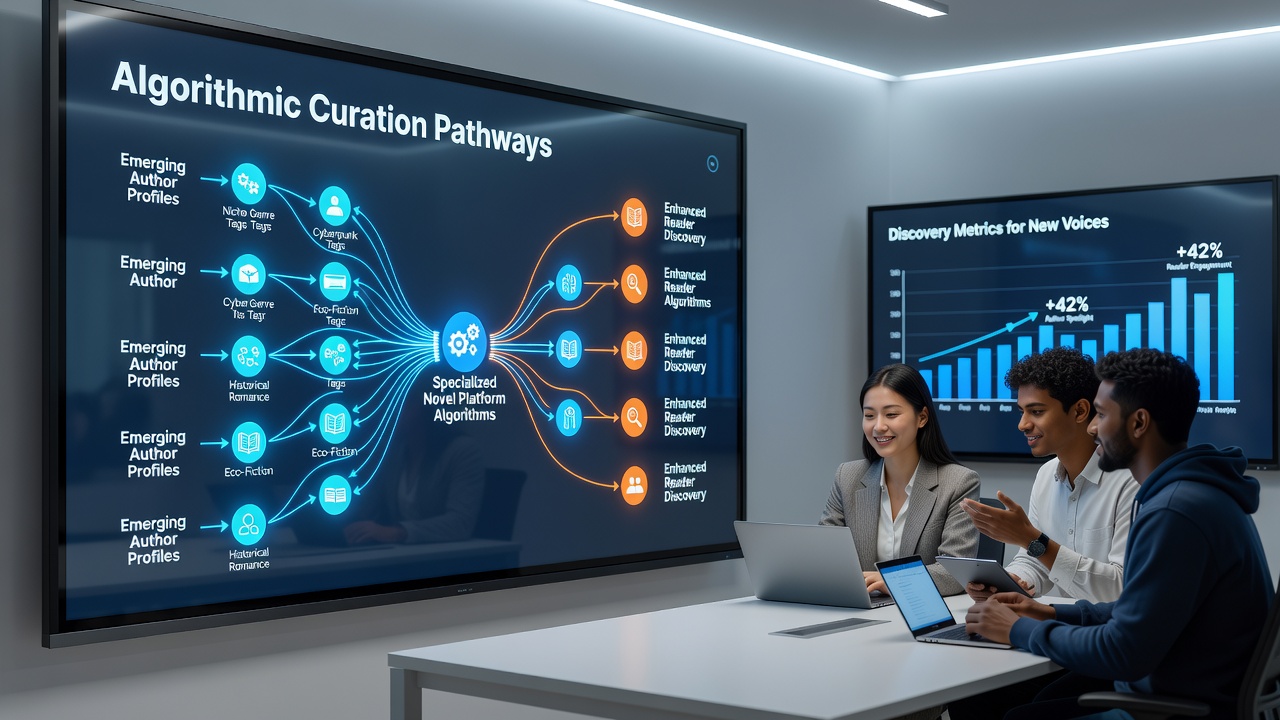
Yet the same systems can create feedback loops where early momentum determines long-term outcomes, and authors who miss the initial recommendation window face steeper climbs. Studies conducted by academic teams at institutions in Canada and the European Union have tracked these patterns across multiple platforms, revealing that algorithmic amplification tends to concentrate attention on a subset of titles even when thousands of new stories upload daily. In September 2026 several platforms introduced additional transparency features that let authors view which signals contributed to their ranking position, a change that followed regulatory discussions in multiple jurisdictions about accountability in automated content distribution.
Comparative Approaches Across Regions
Platforms operating under different regulatory environments adopt varying curation priorities. European operators have incorporated requirements tied to the Digital Services Act that emphasize user control over recommendation criteria, while North American services often emphasize engagement maximization with fewer mandated disclosures. A report from the Australian Government’s Department of Industry, Science and Resources outlines how local platforms experimented with hybrid models that blend algorithmic suggestions with editor-curated lists, resulting in higher retention among readers who discovered new authors through both channels. These experiments demonstrate that algorithmic curation does not operate in isolation and that platform operators adjust parameters in response to both commercial incentives and external policy pressures.
Additional data from the OECD’s work on algorithmic systems shows that transparency measures correlate with increased trust among content creators, particularly when authors receive clear explanations for why certain stories receive promotion. Platforms that publish high-level summaries of their ranking logic have recorded modest increases in author retention rates compared with those that maintain fully opaque systems.
Conclusion
Algorithmic curation shapes discovery pathways on specialized novel platforms by processing engagement data at scale and routing readers toward stories that match predicted interests. The mechanisms reward retention metrics and similarity patterns, which in turn determine how quickly emerging authors accumulate audiences. Regional policy differences influence the degree of transparency and control built into these systems, while platform-level adjustments continue to evolve in response to both performance data and regulatory expectations. Authors who understand the signals that drive recommendations can align their posting strategies accordingly, yet outcomes still depend on reader behavior that remains outside any single writer’s direct control.